Skip to content
Frederico FrazãoGet in touch

Senior DevOps / SRE Engineer

Frederico Frazão

I build and run platforms that have to stay up. SRE, Kubernetes, Terraform and observability, for 20+ years, on-premises and in the cloud.

📍 Portugal · remote

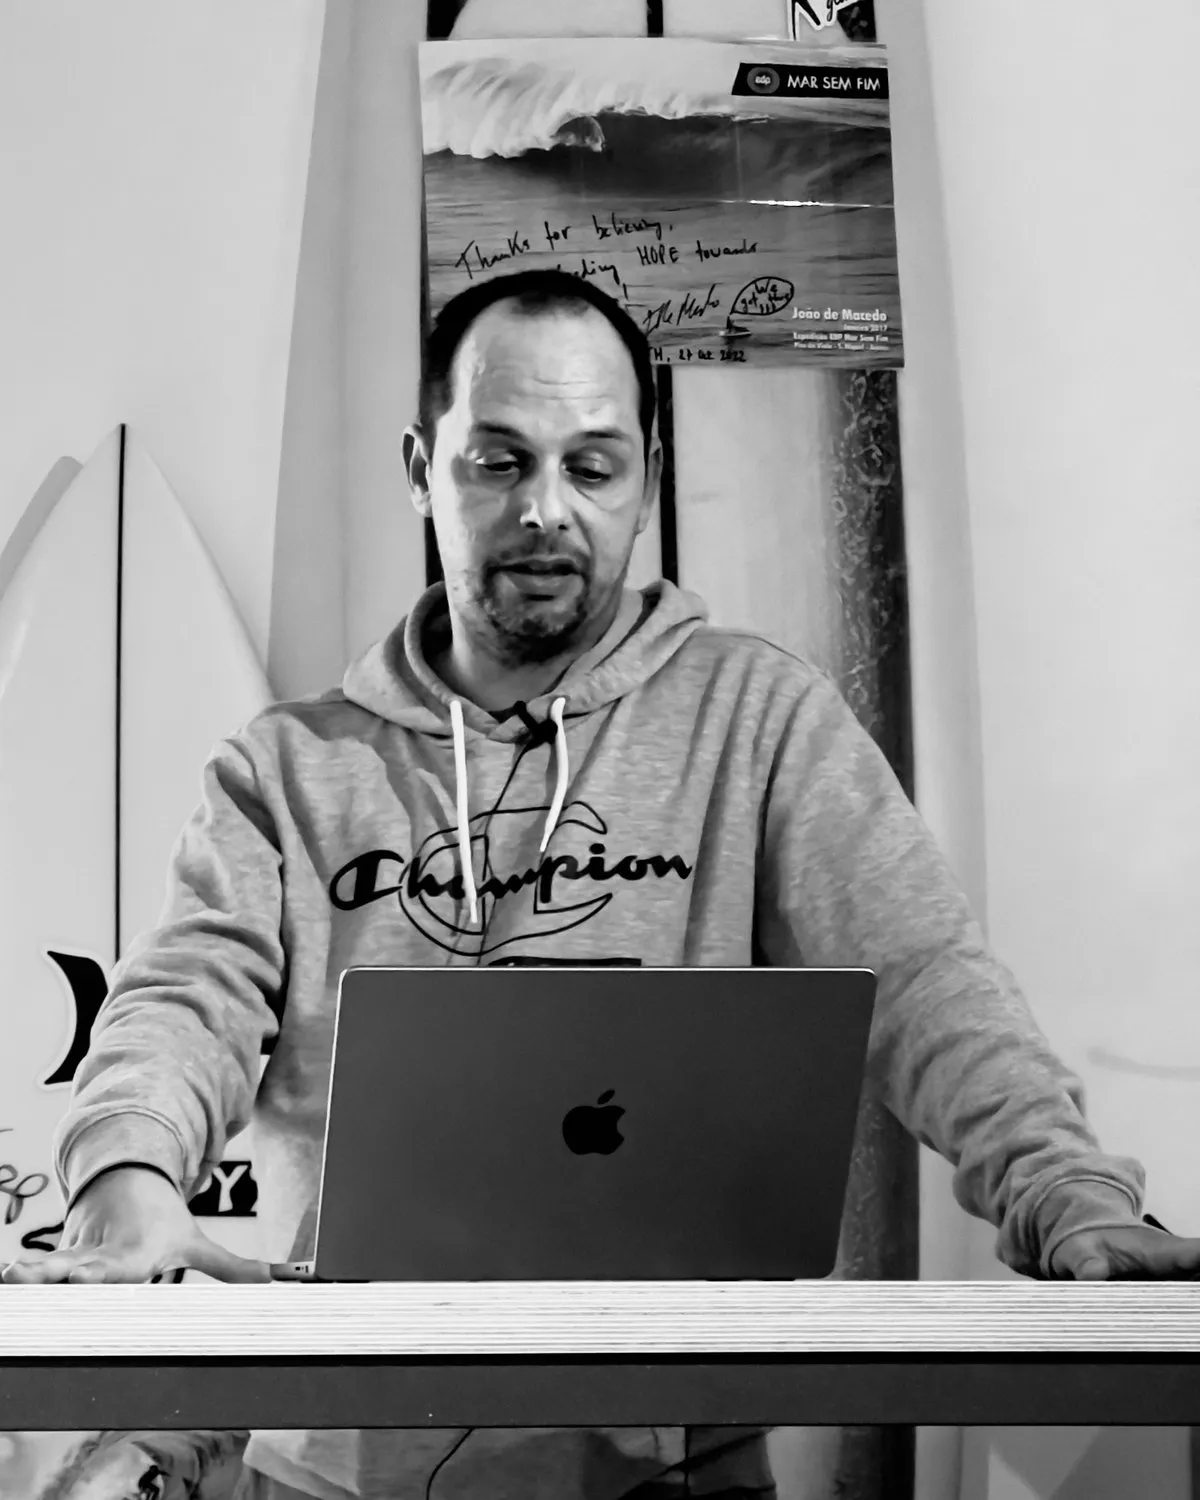
Frederico Frazão giving a talk

20+

years in infrastructure

99.9%

uptime for GitLab & Artifactory

−40%

incident resolution time

−35%

MTTR on 24/7 on-call

About

Reliability is a team sport.

Senior DevOps / SRE engineer with 20+ years building and running platforms that have to stay up, on-premises and in the cloud, including several years leading SRE and DevOps teams.

I build and mentor SRE teams, define SLOs and reliability standards, and keep platform resilience tied to business priorities, across Azure, AWS and GCP with Kubernetes, Terraform, CI/CD and GitOps.

I stay hands-on with observability and automation, and I care about the outcomes: fewer incidents, shorter MTTR and lower infrastructure cost.

Portuguese (native)English (fluent)Spanish (professional)

Experience

Where I've been keeping things up.

  1. Senior DevOps Engineer

    xgeeks · DevOps/SRE lead inside Mercedes-Benz platform teams · full remote

    Oct 2023 – Present

    • Built zero-downtime GitLab upgrade automation with Ansible across three environments and two regions: downtime went from ~2 hours every two weeks to twice a year, and failed deployments dropped by ~30%.
    • Kept GitLab, Artifactory and Crowd at 99.9% uptime, and implemented GitLab Geo disaster recovery in a second region with replication-health alerting.
    • Built the Datadog observability layer for the Git and artifact platforms: 50+ dashboards and monitors with runbooks across three AWS accounts.
    • Built production EKS clusters from an empty AWS account with Terraform and ArgoCD, plus browser-based dev environments with Karpenter, Kyverno and idle shutdown.
    • Cut infrastructure costs by ~15% across Azure and AWS with scale-to-zero for non-production, load-tested right-sizing and storage lifecycle policies.
    AWSEKSKubernetesKarpenterKyvernoArgoCDTerraform EnterpriseAnsibleGitLab GeoDatadogArtifactoryPython
  2. DevOps Engineer Team Lead

    WTX · Part of the Mercedes-Benz Group · full remote

    Jun 2022 – Sep 2023

    • Ran the DevOps and SRE function for a fully remote engineering organization, setting strategy and technical direction for every product team.
    • Cut incident resolution time by 40% and brought monthly downtime from ~5 hours to ~1 hour, through standardized incident process and root-cause fixes.
    • Defined SLOs for the critical services, tied to business priorities and error budgets.
    • Built the Azure platform in Terraform (AKS, PostgreSQL, Synapse, Azure ML, Cloudflare), with ephemeral preview environments and self-hosted runners on Kubernetes.
    AzureAKSTerraformGitHub ActionsActions Runner ControllerHashiCorp VaultDatadogCloudflare
  3. Site Reliability Engineer Team Lead

    Mercedes-Benz.io · Full remote

    Jan 2022 – May 2022

    • Led the SRE practice, set reliability standards and got SLOs adopted by product engineering teams.
    • Cut service disruptions by ~30% with automated scaling, redundancy and fault tolerance across products.
  4. Site Reliability Engineer Team Lead

    cloudmobility · Part of the Mercedes-Benz Group · full remote

    Jul 2021 – Dec 2021

    • Built the observability stack on Prometheus, Alertmanager, Grafana and Thanos, federated across four zones with alerting to Opsgenie.
    • Set up on-call and incident management from nothing, and standardized deployments on FluxCD and Helm.
    • Ran Kubernetes on bare metal and GKE (RKE, Ceph, Cilium, MetalLB, Keycloak, Harbor, Vault).
    KubernetesFluxCDHelmPrometheusThanosGrafanaGKECephCilium
  5. Site Reliability Engineer

    Sky Technology Centre · Media and OTT platforms · hybrid Linux and Windows

    Feb 2016 – Jun 2021

    • Covered 24/7 third-level on-call and brought MTTR down by ~35%.
    • Automated zero-downtime releases across two datacenters, shifting traffic on the F5 global load balancer while each site was rebuilt and tested.
    • Built the data tier as code: PostgreSQL HA (repmgr, PgBouncer), a Redis cluster and sharded MongoDB with Terraform and Ansible.
    • Automated provisioning and configuration, cutting deployment time by ~50%.
    TerraformAnsiblePuppetJenkinsTeamCityVaultF5 BIG-IPSplunkDynatraceKafka
  6. Senior Consultant

    agap2 · Banking and insurance: MillenniumBCP Ageas, CGD / Fosun, GNB Seguros Vida

    Oct 2009 – Feb 2016

    • Built Dev, QA and Prod infrastructures on Azure and migrated on-premises workloads within regulatory constraints.
    • Automated Azure provisioning in PowerShell (SQL Server AlwaysOn, SharePoint, failover clusters) and cut non-production cost with scheduled runbooks.
    • Wrote a ~40-function PowerShell module that turned recurring operations work into scripted runs.
  7. Earlier

    • System Administrator, Spidernet · 2006 – 2009 · Main client Nestlé Portugal, ~2,500 users
    • Systems & support, Megamicro · Germinus XXI · WTS · Maxitel · 1998 – 2005

Skills

The toolbox.

SRE & Reliability

SLOs / SLIsError budgetsIncident managementOn-callRCAMTTR

Cloud & Kubernetes

AWSAzureGCPEKS / AKS / GKEKarpenterKyvernoCiliumHelmArgoCDFluxCD

IaC & Automation

TerraformTerraform EnterpriseOpenTofuAnsiblePuppetAtlantisGitHub ActionsGitLab CIJenkins

Observability

PrometheusGrafanaLokiThanosDatadogSplunkOpenSearchAlertmanagerOpsgenie

Data

PostgreSQL HAMongoDB shardingRedis ClusterKafkaSQL Server AlwaysOn

Security

mTLS & private PKIHashiCorp VaultSAST / IaC scanningSBOMAWS Network Firewall

Platforms

GitLab (Geo, Gitaly, KAS)ArtifactoryF5 BIG-IPHAProxyVMwareBare metal (MAAS, Ceph)

Code & AI

PythonBashPowerShellGoMCP serversLLM agents with guardrails

Open source

Upstream contributions.

  • GitLab

    Fixed the Gitaly version check so upgrades run without downtime, corrected the settings API docs, and documented 56 missing rate-limit attributes.

  • GitLab Go API client

    Added 50 missing rate-limit settings, released in v3.17.0.

  • GitLab Terraform provider

    Added the integration allow-list settings and 76 rate-limit settings with version-gated acceptance tests, and fixed the acceptance test that broke the EE CI after GitLab 19.4 made project transfers asynchronous.

  • Argo CD · AzureRM provider · others

    A merged test fix in Argo CD, a docs fix for PostgreSQL point-in-time restore in the AzureRM provider, and merged fixes in a Home Assistant integration and a GitHub Action.

Side projects

Built for fun, run like production.

  • SRE automation bot

    A Slack-controlled platform in Python (FastAPI, PostgreSQL) with role-based access, approval-gated actions and a fail-closed action engine, covered by 570 tests. Changes run through outbound workers over mTLS that only execute allow-listed capabilities.

  • Homelab SRE platform

    A single-board computer and two VPSs run with Ansible and Docker Compose: 44 Grafana dashboards and 80 alert rules as code, encrypted backups with automated restore drills, and signed multi-arch releases with SBOM.

  • AI for incident diagnosis

    A read-only MCP server that lets an LLM investigate GitLab and Artifactory incidents with 13 tools and 43 root-cause rules, and generates weekly health reports.

  • Luz Indexada for Home Assistant ↗

    An open-source HACS integration with the real 15-minute electricity price for Portuguese indexed tariffs: the cheapest time window, a supplier comparison with estimated monthly cost, local caching to keep API calls low, tests in CI, and English and Portuguese UI.

  • Hybrid Forge Lab ↗

    My lab for small, reliable APIs and tools, like the MailForge email-validation API.

Let's talk reliability.

Platforms, SRE practices, or just to say hi. The fastest way to reach me is by email.